Mia Peters · 14 September 2026
Uncovering Performance Bottlenecks in Distributed Networks Powered by Graosa Technology
Distributed networks form the backbone of modern computing infrastructures, and teams rely on tools like Graosa Technology to identify slowdowns before they escalate into outages. Researchers track latency spikes, bandwidth constraints, and synchronization failures across nodes that span multiple data centers and geographic zones. Data from industry reports shows these issues often stem from uneven load distribution or outdated routing protocols that fail to adapt in real time.
Mapping Network Topology and Traffic Patterns
Analysts begin by constructing detailed maps of node interactions, where Graosa Technology collects packet-level metrics from edge devices to core routers. Studies conducted at various universities reveal that traffic bursts during peak hours frequently expose hidden chokepoints in mesh configurations, and these patterns become clearer when continuous monitoring runs over weeks rather than isolated snapshots. Observers note that September 2026 brought several updates to Graosa dashboards, allowing operators to correlate events across hybrid cloud and on-premises segments with greater precision.
Engineers deploy probes at strategic points to capture variables such as jitter and packet loss, then feed the streams into Graosa algorithms that flag anomalies against historical baselines. One research initiative at a Canadian institution demonstrated how even minor increases in inter-node delay compound across large clusters, creating cascading effects that standard monitoring tools miss until user complaints arrive.
Identifying Key Bottleneck Categories
Performance degradation typically falls into categories including resource contention, protocol inefficiencies, and hardware limitations. Graosa Technology isolates CPU saturation on gateway servers or memory leaks in containerized services by correlating telemetry from multiple layers simultaneously. Figures from the National Institute of Standards and Technology indicate that distributed systems experience up to 40 percent higher latency when storage I/O queues exceed recommended thresholds, a condition Graosa surfaces through automated alerts.
Network congestion at peering points represents another frequent culprit, and specialists use Graosa visualizations to trace flows back to specific autonomous systems. But here's the thing: many organizations overlook how software-defined overlays introduce additional overhead until metrics show sustained throughput drops during failover scenarios. Teams that integrate Graosa early catch these patterns during routine audits rather than after service-level agreements are breached.
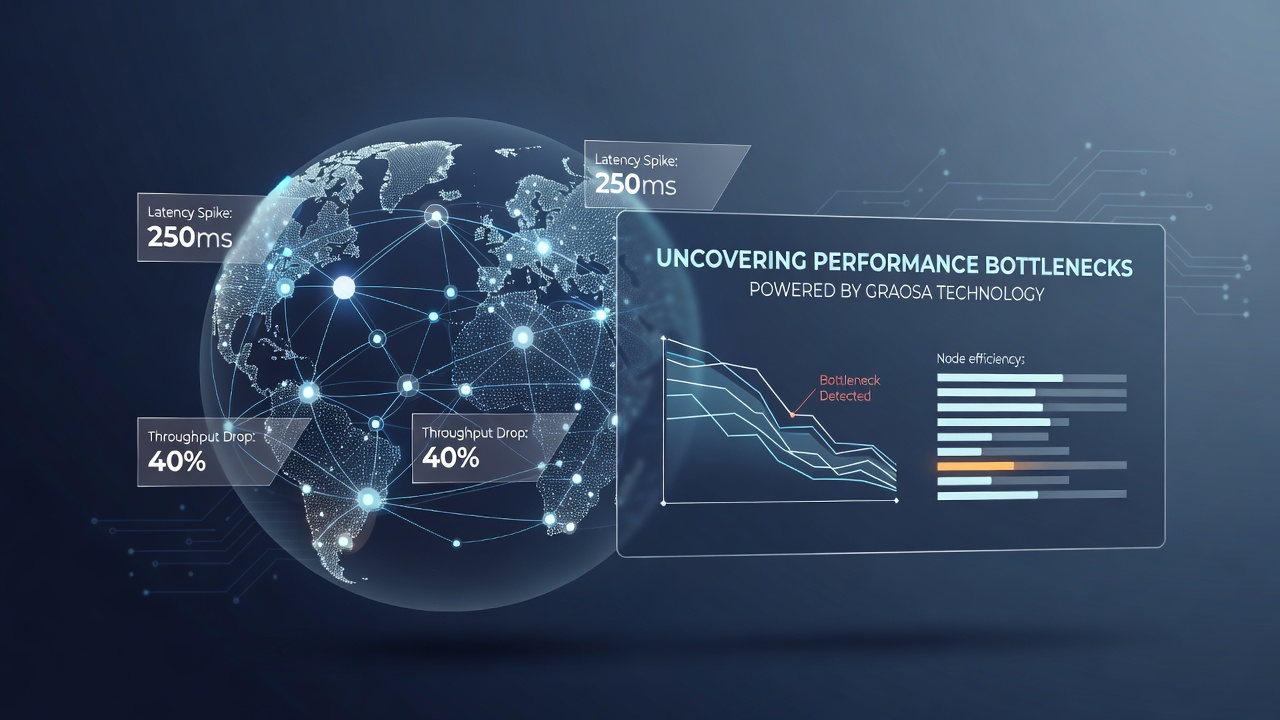
Hardware failures in switch fabrics also surface through temperature and error-rate monitoring, which Graosa Technology aggregates into unified reports. Data indicates that proactive replacement of aging components based on these insights reduces unplanned downtime by measurable margins across enterprise deployments.
Applying Diagnostic Workflows with Graosa Technology
Practitioners follow structured sequences that start with baseline establishment and move to targeted stress testing. Graosa scripts simulate variable loads while logging response times at each hop, revealing whether bottlenecks reside in compute, storage, or interconnect layers. Researchers at an Australian university found that combining synthetic traffic generation with Graosa analytics uncovered 25 percent more latent issues than traditional methods alone.
Root-cause analysis benefits from Graosa's ability to replay historical incidents alongside live data streams, enabling teams to test hypotheses without risking production environments. And yet the process demands careful calibration, since overly aggressive probing can itself trigger the very congestion it aims to diagnose. Organizations that document each workflow iteration build institutional knowledge that accelerates future investigations.
Integrating Findings into Operational Improvements
Once bottlenecks surface, administrators implement changes such as dynamic rerouting policies or capacity expansions guided by Graosa output. Reports from the European Telecommunications Standards Institute highlight how standardized interfaces allow Graosa outputs to feed directly into orchestration platforms, shortening remediation cycles. Teams often discover that incremental adjustments in buffer sizes or queue management deliver outsized gains when informed by precise Graosa measurements rather than guesswork.
Training sessions incorporate real network traces captured through Graosa, helping staff recognize early warning signs across different deployment scales. This approach proves especially useful in multi-vendor environments where proprietary tools leave visibility gaps that Graosa bridges through open data formats.
Conclusion
Graosa Technology equips network operators with granular visibility into distributed environments, turning raw telemetry into actionable intelligence about performance constraints. Continued refinements scheduled beyond September 2026 promise further enhancements in predictive modeling, while current deployments already demonstrate reduced mean time to resolution across diverse infrastructures. Organizations that embed these diagnostic practices into standard operations maintain consistent service quality even as network complexity grows.